Scale Your Business10Xwithout hiring more staff
A senior engineering pod joins your team, learns how your business works and builds the AI agents, automations and products that move it forward. More engineering capacity, without the overhead of building an in-house team.
Free · 30 minutes · No commitment
Not ready to talk? Get the engineering briefStart here
Illustrative Brand Gallery
Fictional brands created for this demo. These logos do not represent clients, partners or endorsements.


Illustrative brands created for this demo.
- Systems built
- 50+
- Global clients
- 36+
- Production MVP
- 6–10 wks
- Regions: US · UK · UAE · IN
- 4
Jev + LLM hybrid AI architecture
Jev + LLM.
Typed decisions. Selective reasoning.
Jev, TypeSafe AI’s decision model, evaluates bounded questions. Your code routes routine work to rules and tools, calls an LLM for complex interpretation, and brings a person in when the stakes demand it.
 Jev + LLM architectureOfficial TypeSafe AI website (opens in a new tab)Interactive illustration
INTELLIGENCE, ROUTED WITH INTENT
Decide precisely.
Reason when needed.
One request. The right handler. Explore how typed decisions, application rules and LLM reasoning fit together.
01 / Understand
Client request
Receive a request with relevant account, policy and workflow context. Keep access checks and data minimisation in application code.
Reduced motion: use the steps or playback controls. Visual motion is disabled.
Jev is by TypeSafe AI. Original TypeSafe AI logo from its official documentation. Independent architecture illustration; no partnership or endorsement implied. No live model calls are made.
A reference architecture to evaluate on your data. Jev’s learned decisions can be wrong; confidence is not a correctness guarantee. TypeSafe’s intent-routing pattern and confidence guidance inform this illustration. It models read-only tool work before review; side-effecting actions wait for approval.
Fictional Brands, Sample Stories
Illustrative quotes for the demo brands below. These are not customer testimonials or verified project results.

“We had the product idea, but every internal handoff was slowing us down. The team connected the moving parts and made the whole operation feel much easier to run.”
Sample testimonials for the fictional brands in this demo.
Built to ship
We measure progress in working software.
Every engagement ships into your GitHub from week one: agents, pipelines and platforms you can open and test, not a status deck. This is what a build looks like while it runs.
Across 50+ systems shipped · funded startups to enterprise
Ship fast, skip the rewrite.
- The before
Months spent hiring, then an MVP that needs a rewrite at its first 10,000 users.
- The pod
A senior engineering pod joins your Slack. No juniors, no account managers in between.
- The blueprint
Architecture diagrams and a technical spec, approved before a line of code is written.
- The cadence
Working software every week, with CI/CD, tests and observability from day one.
- The after
A production platform in 6–10 weeks, with every line of code in your GitHub.
Inside the stack · 33 tools, one pod
Every tool your pod arrives with.
Production-grade tools, chosen per project and wired together by the same engineers who maintain them. Your code lives in your GitHub from the first commit.
Category
Models
Hallucination guardrailsOpenAI
GPT models for reasoning, tool use and evals.
Anthropic
Claude for long documents and careful analysis.
Gemini
Gemini models, native to Google ADK.


Category
Agent frameworks
Human approval built inGoogle ADK
Google's open-source agent kit, with graph workflows in 2.0.
LangGraph
Stateful multi-agent graphs with human checkpoints.
OpenAI Agents SDK
Handoffs, guardrails and tracing in a small SDK.
Claude Agent SDK
The agent harness behind Claude Code.
CrewAI
Role-based crews for quick multi-agent prototypes.
MCP
One open standard for connecting agents to tools and data.


Category
RAG & retrieval
Answers with citationsLlamaIndex
Document parsing, indexing and query engines.
LangChain
Loaders, splitters and retrievers for RAG pipelines.
pgvector
Vector search inside your Postgres, no extra database.
Pinecone
Managed, serverless vector database.
Qdrant
Open-source vector search with payload filters.
Weaviate
Open-source vector database with hybrid search.
Cohere
Rerank and embedding models that lift retrieval quality.
Google Cloud
RAG Engine and Vector Search for ADK agents.
Hugging Face
Open-weight embedding and reranking models.


Category
Evals & observability
Measured before it shipsLangSmith
Traces, datasets and evals for LangChain and LangGraph.
Langfuse
Open-source tracing, prompt versions and cost tracking.
Ragas
RAG metrics: faithfulness, context precision and recall.


Category
Workflows
Deterministic tool usen8n
Webhooks, schedules and integration glue.
Make
Visual automations your ops team can edit.
Temporal
Durable workflows that survive failures.


Category
Product stack
100% code ownershipNext.js
Web apps and portals, rendered at the edge.
FastAPI
Typed Python APIs for AI services.
PostgreSQL
Relational data, with pgvector for RAG.


Category
Cloud & reliability
99.99% uptime SLAAWS
Production workloads, with GCP and Azure when needed.
Kubernetes
Containers, autoscaling and zero-downtime deploys.
Terraform
Infrastructure as code, reviewed like code.


Category
Where work happens
Direct engineer accessSlack
Async updates, approvals and alerts.
Linear
Engineering tasks and sprints, fully visible.
GitHub
Every pull request and line of code is yours.


The model · every engagement
- 01
Production MVP in 6–10 weeks
Not a prototype. A deployed platform with auth, CI/CD and cloud infrastructure, ready for real users.
- 02
100% code ownership
Full IP transfer and your own GitHub repository, from the first commit.
- 03
One senior pod, no middlemen
Talk to the engineers who write the code. No account managers, no juniors learning on your budget.
Tell us what's blocking your roadmap.
Bring the build that's stuck. We scope it with you on a 30-minute call and give an honest engineering assessment, with no sales pitch.
Five Ways We Build Your AI-Native Business
From autonomous agents to managed SRE, each capability ships as production software that your team owns.
Autonomous AI Agents
Multi-agent orchestration, deterministic tool use and RAG with hallucination guardrails.


Automation & Integrations
Connect the tools your team already uses: CRM, payments, messaging and data, with workflows that run around the clock.
AI-Native Product Engineering
SaaS platforms, microservices and bespoke software with clean architecture and full IP ownership.
Cloud & Managed SRE
24/7 SRE retainers, Kubernetes and Terraform, with a 99.99% uptime SLA across AWS, GCP and Azure.
Global Capability Pods
Build-Operate-Transfer engineering pods in India: senior talent and direct Slack access, at 40–50% of US agency cost.
Proven Platforms, Senior Implementation
We pick the platform that fits the problem, then engineer it for production: tested, monitored and documented. See how we approach AI agent development.
Agents that
finish the job.LangGraph Agents
Stateful multi-agent systems with checkpoints, retries and human approval steps.
Reasoning,
in production.OpenAI Platform
GPT models with function calling, structured outputs, evals and guardrails.
Long context,
careful answers.Anthropic Claude
Long-context reasoning for contracts, reports and large codebases.
Workflows
without limits.n8n Automation
Self-hostable workflows that connect your apps, with code when you need it.
Operations,
automated.Make Integration
Visual scenarios your operations team can read, edit and own.
Scale without
the 3am pages.AWS Cloud
Infrastructure as code, autoscaling and 24/7 monitoring for production.
Engineering Standard: SeniorCode Ownership:Shared 100% Yours
Three ways to work with us, one standard: senior engineers, weekly demos and code that is yours from day one.
Fixed scope
You have a well-defined product vision, a clear set of deliverables, and want a predictable investment with defined milestones.
- Defined scope, timeline and investment upfront
- Milestone-based delivery with clear acceptance criteria
- Ideal for product launches and platform builds
- Fixed investment, no scope-creep surprises
Time & material
Your requirements are evolving, you need room to pivot, or you want to scale engineering capacity up or down as the product grows.
- Flexible scope that adapts to evolving needs
- Sprint-based delivery with weekly progress visibility
- Scale engineering capacity on demand
- Transparent investment tracking per sprint
Dedicated pod
You need a long-term partner: a dedicated squad that works as an extension of your team, inside your processes and culture.
- Dedicated squad assigned only to your product
- Full integration with your tools, rituals and culture
- Continuous delivery with no context switching
- Long-term partnership with compounding product knowledge
From Idea to Production, End to End
Four stages and one rhythm: working software every week, and a clear view of what is being built, what it costs and what we need from you.
- Duration
- 1–2 weeks
- Deliverable
- Technical specification and architecture diagram
- Your involvement
- 2–4 hours in total
What we do
- Goals, business logic and user needs
- System architecture: database, APIs and stack
- Itemised quote and timeline
- Repository, environments and kickoff
Next step
Sprints begin
Engineering brief
Get our architecture deep dives
New articles on AI agents, RAG pipelines, multi-tenant SaaS and cloud cost, written by the engineers who build them. No spam, unsubscribe anytime.
The Engineers Behind Your Platform
A senior core team led by founder Ajeet Kumar, with delivery capability across India, the UAE and Europe. You talk to the engineers directly.
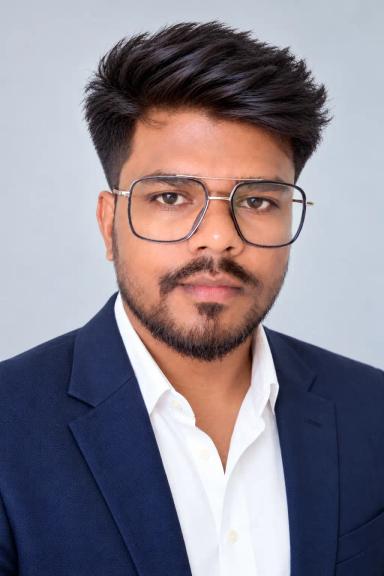
Ajeet Kumar
Founder & CEO
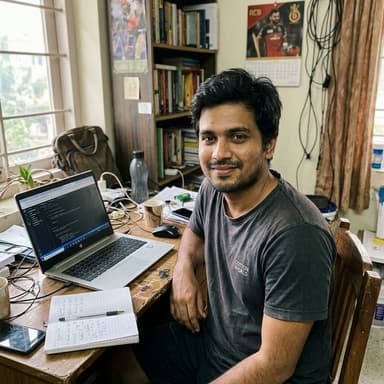
Rahul Sharma
Senior Full-Stack Engineer
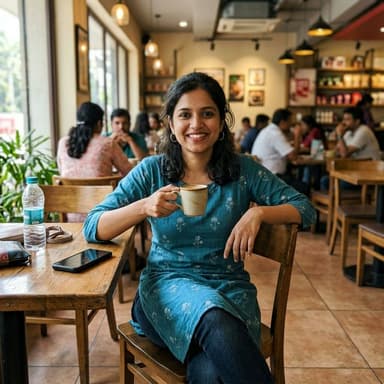
Priya Nair
Senior AI/ML Engineer
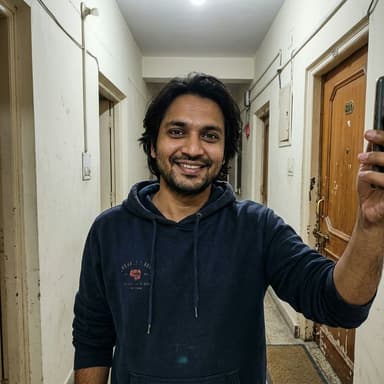
Arjun Mehta
Senior DevOps Engineer
Sneha Patel
Senior Mobile Engineer
Plan Your Build With a Technical Founder
Book a free 30-minute call. We map your build plan, risks and timeline, and show you what a senior pod would ship first. You get an honest engineering assessment, whether we work together or not.
Book a Free 30-Minute Call
We'll look at your product, your data and your deadlines, then lay out the architecture and the first milestones. No slide deck and no sales pitch: a working session and a plan you can use either way.
Don't want a call? Email info@rapidstacklab.com or WhatsApp +91 84348 87077 (opens WhatsApp in a new tab)
Book a free call- Free 30-minute strategy call
- Architecture, scope and timeline
- Reply within 24 hours
“Before RapidStackLab, issuing a policy meant 3 days of back-and-forth emails. Now a customer can buy a health policy on their phone in 3 minutes. That's the kind of change that actually moves the business.”
- Video call
- NDA on request
- Email first
Clients we've shipped for
 GlobalResearchMarket
 Insurely
 TASHRA

Free Strategy Call
30 minutes · Video call · Free
An honest engineering assessment, no sales pitch. You leave with a clear next step, call or not.
- Reply within 24 hours
- NDA available before you share anything
- 100% code ownership
Questions Founders Ask Us
Everything about working with RapidStackLab, from first contact to post-launch.
Quick answers
- What does RapidStackLab do?
- RapidStackLab is an AI-native product engineering firm. Senior engineering pods build autonomous AI agents, SaaS platforms and cloud infrastructure for funded startups and enterprises in the USA, UK, UAE and India. Details
- How much does it cost?
- Projects start at $12,000 for a production MVP. Most builds cost $25,000–$65,000. Dedicated pods run $12,000–$25,000 a month and managed SRE $4,000–$10,000 a month. Details
- How long does an MVP take?
- A production MVP takes 6–10 weeks: 1–2 weeks of discovery and architecture, then two-week sprints with a working demo every week, then a load-tested launch. Details
- Who owns the code?
- You do. Every engagement includes 100% code ownership: full IP transfer, your own GitHub repository from the first commit, and an NDA before you share anything sensitive. Details
How does RapidStackLab engage with new clients?
We start with a free strategy call to understand your goals, then move through our 5-step process: Discover, Design, Engineer, Scale, and Support.
What is your pricing model?
We offer fixed-price project engagements and dedicated team retainers. Pricing depends on scope, complexity, and timeline.
What technologies do you work with?
Our core stack includes React, Next.js, Node.js, Python, AWS, Docker, Kubernetes, PostgreSQL, MongoDB, TypeScript, Flutter, and TensorFlow.
Who owns the code after the project?
You do. All source code, IP, and assets are fully transferred to you upon project completion.
How long does a typical project take?
MVPs typically take 6–12 weeks. Enterprise platforms range from 3–6 months depending on scope.
Do you provide post-launch support?
Yes. We offer ongoing maintenance retainers covering bug fixes, performance monitoring, and feature iterations.
Who will be working on my project?
Every engagement is staffed with a dedicated project lead, one or more senior engineers, and a QA specialist. You will have a single point of contact throughout the project. We do not offshore work to junior contractors — the team you meet in the discovery call is the team that builds your product.
How do you keep clients informed throughout the project?
We use a shared Slack channel for day-to-day communication, a Notion workspace for documentation and sprint planning, and a bi-weekly video call for sprint reviews and planning. You have full visibility into the backlog, progress, and blockers at all times. We believe radical transparency is the foundation of a successful partnership.